researchcogny's own data
what we measured.
Data Cogny publishes about itself and about the tools marketers use. Each page says how it was made and when. Use it, cite it, check it.
01studies
- Verdict ledger
167 of Cogny's own marketing changes and how each one turned out: 70 worked, 78 partial, 19 didn't work.
data as of 2026-10-20 - AI visibility index
50 marketing questions asked to ChatGPT, Claude, Gemini and Perplexity: who gets recommended. Cogny came up in 5 of 45 non-brand questions.
run 2026-10-14 - The truth ledger
Six months of measured customer outcomes, checked against Search Console, GA4 and order data.
case study
02cogny bench
Our own benchmark of AI models on marketing-analytics problems with traps in the data: score against cost per run, published as each model ships.
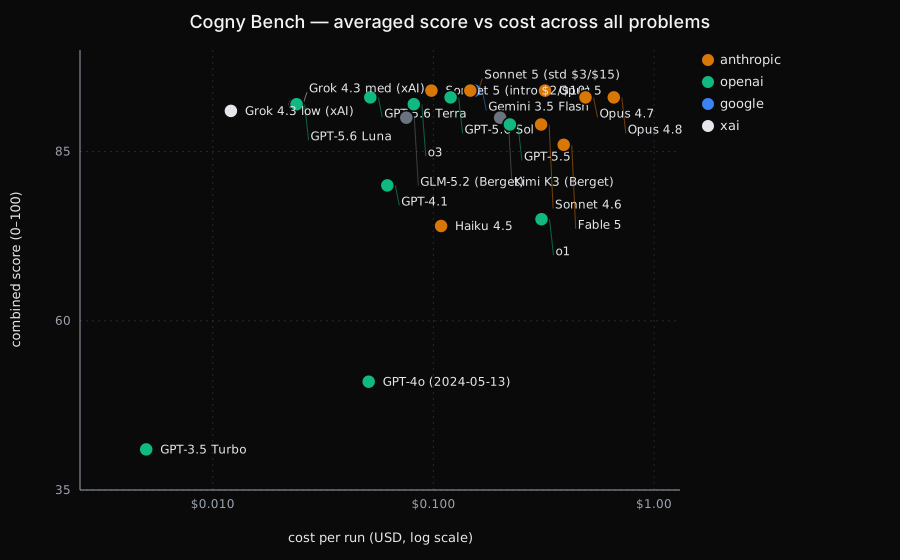 2026-07-30Kimi K3 and Opus 5 on Cogny Bench: A Bigger Open Model Isn't a Better Buy
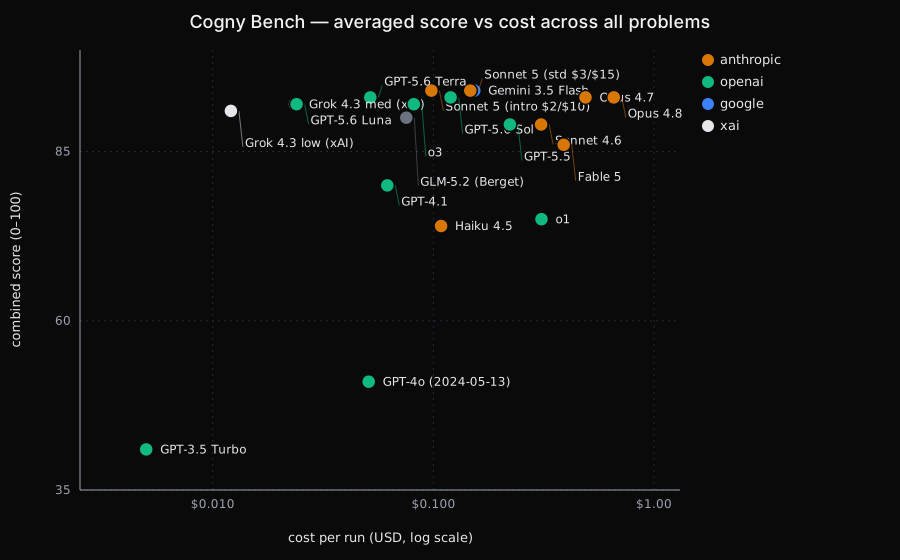 2026-07-10GPT-5.6 on Cogny Bench: Terra Matches Opus 4.8 at $0.05 a Run
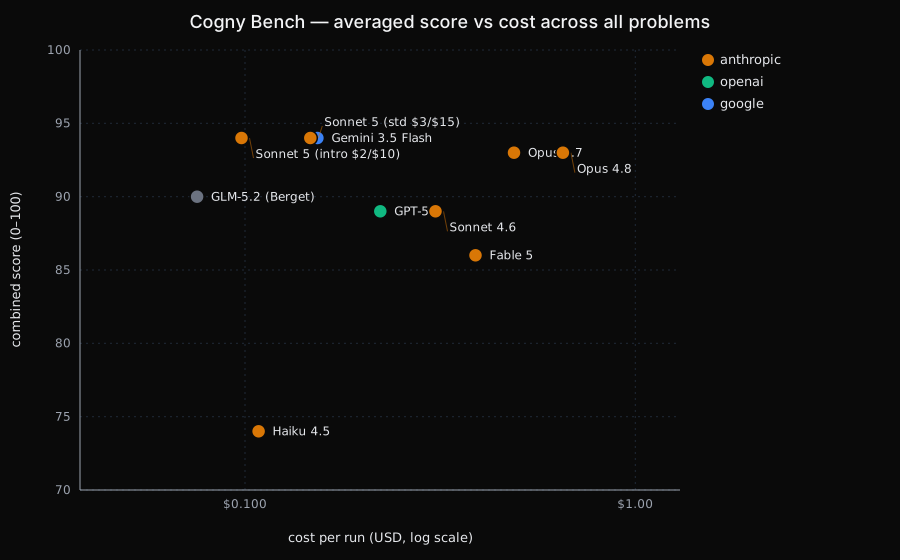 2026-07-02Claude Fable 5 on Cogny Bench: When the Flagship Isn't the Value Pick
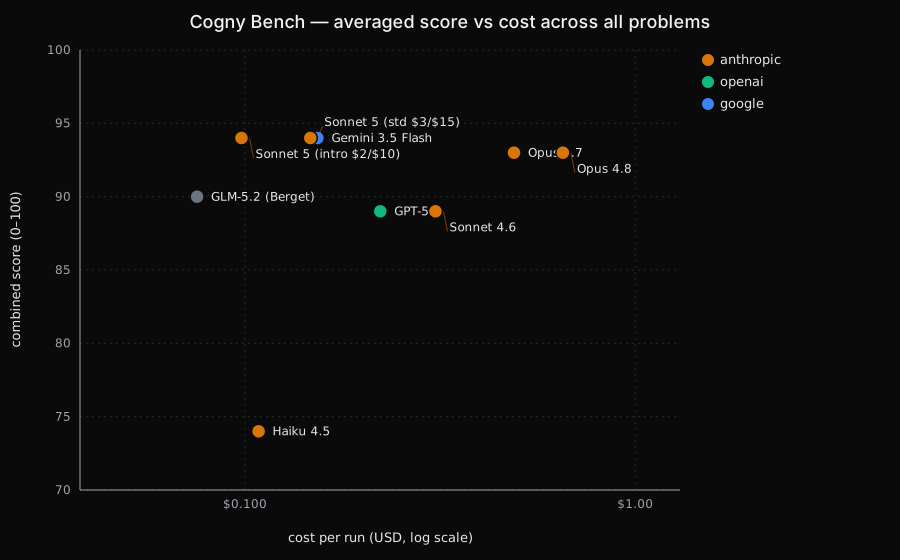 2026-06-30Claude Sonnet 5 on Cogny Bench: Frontier Accuracy at a Sonnet Price
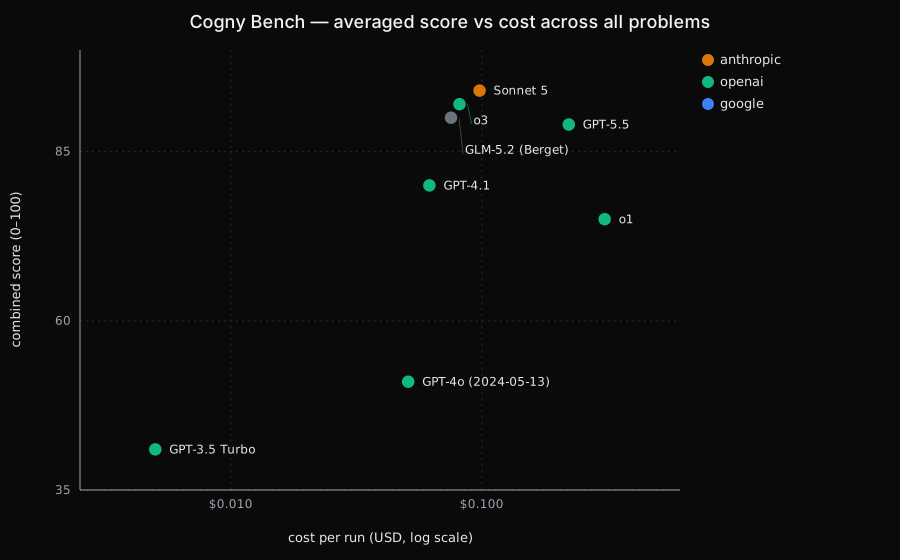 2026-06-29The Capability Arc: Running Cogny Bench Across Six OpenAI Models, 2023 → 2025
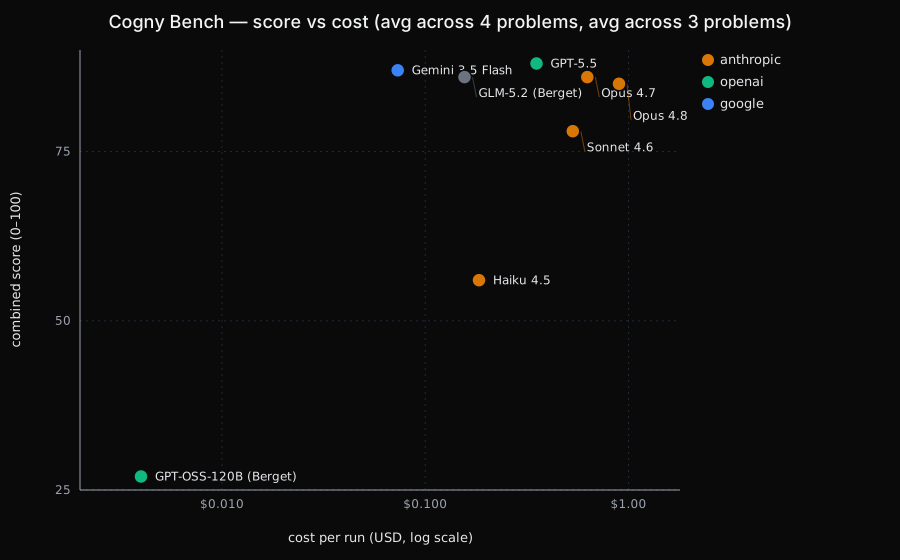 2026-06-24Cogny Bench: Why We Built Our Own Frontier-Model Eval (And Why It Paid Off This Week)